E-commerce
AI Alignment Infrastructure
Make AI alignmentan in-house capability
An agent-powered platform that puts your enterprise'sexpert judgment to work shaping how AI behaves and improves.
The challenge
Aligning AI with your enterprise's context and taste can build a moat against frontier models, but sustaining it requires continuous effort, and relying on external teams for every improvement puts that advantage at risk.
How we address
Teammately equips your experts and AI engineers to align and improve AI themselves, at scale.
Learn moreWHAT YOU GAIN
Your moat can become a benchmark, a granular PRD co-authored with your experts, to drive AI improvements.
Retail
Store Associate Tastes Bench
Agent
Customer Goal Completion Bench
Customer support
Successful Escalation Bench
Customer Support
Legally Sensitive Context Bench
Your domain
Your bench, built with your experts
Decision evidence
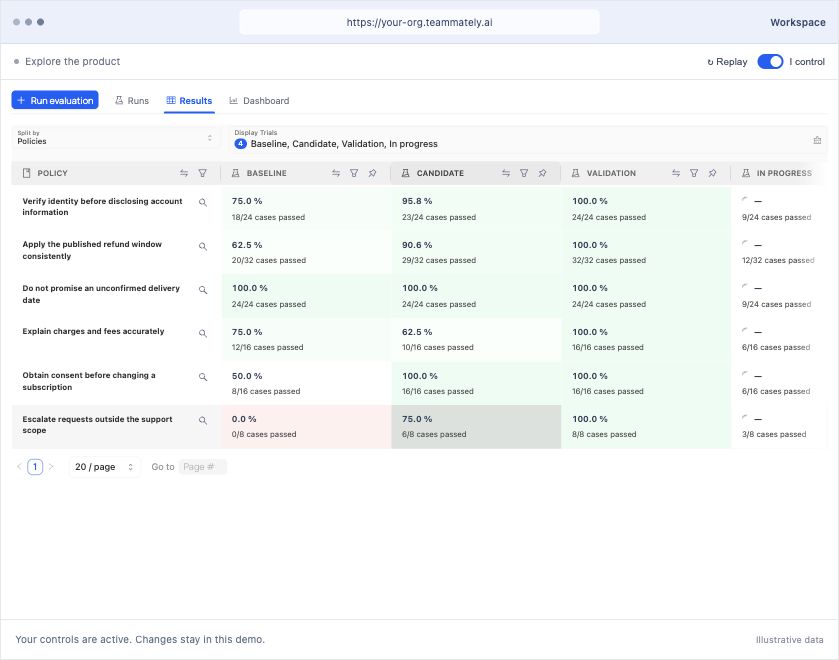
Apply expert rubrics to outputs and recorded trajectories. Compare candidates by policy, rubric, and coverage, with each judgment connected to its criteria and the behavior assessed.Explore Trialground
Harness prototype
Lemon Goal investigates failures, develops competing harness prototypes in a sandbox, and tests them through Trialground. It pursues the behavior you want to improve while tracking protected requirements, permitted changes, and the search budget. Engineers receive tested candidates and the evidence behind them.Explore Lemon Goal
Datasets for training
For SFT, synthesize target responses around policy boundaries, exceptions, and missing information. For DPO, construct preferred and rejected responses to the same input, with the preference grounded in expert rubrics. Each example has a specific teaching purpose.Explore Lemon Weave
“A real product needs its own definition of success. Human reviewers have to explain what’s good or bad and why. Then you have to check whether the AI judge agrees.”
“We have the technical expertise to improve AI, but how we improve it depends on business context and domain knowledge. Bringing that knowledge into the development process is a major challenge.”
ARCHITECTURE
How Alignment Infrastructure works
Alignment Situations
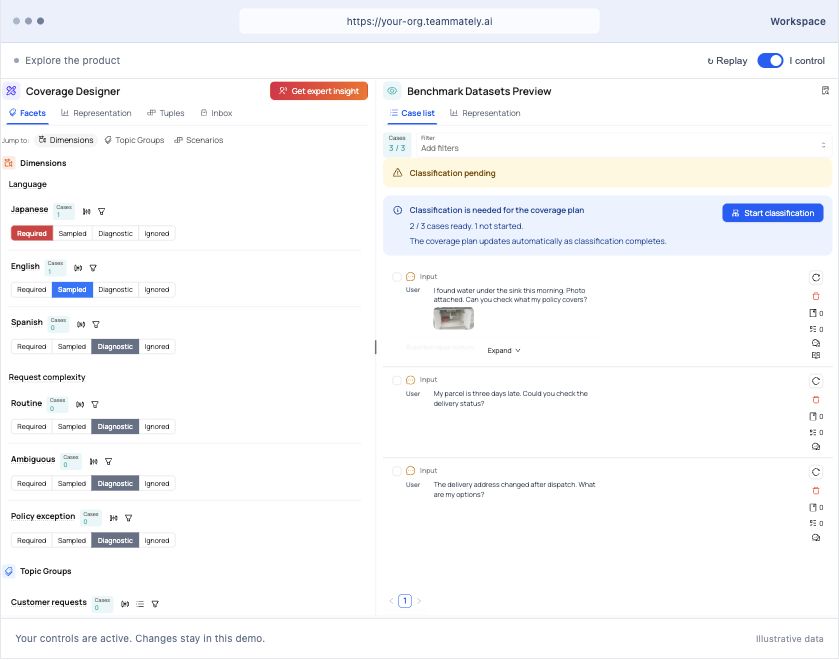
Design benchmark coverage and case
Build benchmarks around the situations your AI must handle, combining Topics, Scenarios, and the ontologies within Dimensions into deliberate coverage. Lemon finds and synthesizes cases with the supporting artifacts and worlds those situations require, while production interactions help your team identify gaps and evolve coverage.
Alignment Elicitation
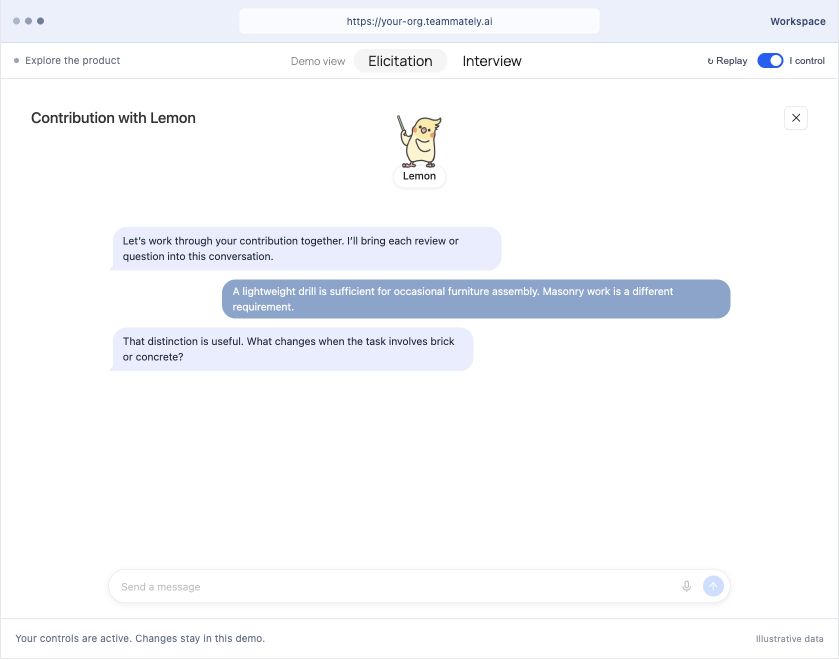
Elicit expert judgment at scale
Bring your experts’ tastes, preferences, reasoning, and tacit knowledge into how your AI improves. Lemon leads adaptive case reviews, conversations, and voice interviews to uncover the judgment behind their decisions. Those insights inform shared policies and rubrics grounded in each case, forming benchmarks that guide AI development toward the behavior your enterprise expects.
Alignment Actualization
Evaluate with rubrics and build toward your north star
Put your benchmarks to work to evaluate and improve your AI. Stress-test untrusted harnesses, weights, and adversarial prompts in Trialground’s managed, isolated sandboxes; rubric evaluations guide model, prompt, configuration, and tool choices. Lemon Goal autonomously builds harness prototypes toward benchmark goals within your constraints. Lemon Weave augments datasets for weights training, guided by expert policies and rubrics.
Meet Lemon,Agent for enterprise alignment
Lemon undertakes the preparation, inquiry, construction, and investigation behind AI alignment. Your team reviews its proposals, examines the results, and decides what moves forward.
Adaptive learning and follow-up questions
Learns from each expert response, probes the reasoning and exceptions, and develops findings into proposed policies and rubrics.
Interview over voice
Conducts live conversations so experts can explain context, taste, and trade-offs aloud, then develops their reasoning into proposed standards for review.
Synthesize cases that matter
Builds cases, controlled alternatives, and supporting artifacts around your coverage, making rare conditions and subtle decision boundaries available for expert review and evaluation.
Learn from context and logs
Uses project materials and production logs to propose coverage dimensions, identify missing combinations, and keep benchmark representation connected to changing user needs.
Find better harnesses in Goal mode
Investigates benchmark failures, develops competing harness prototypes, and tests them in sandboxes, giving engineers candidate changes with clear gains and regressions.
Augment datasets for training
Expands expert policies and rubrics into SFT demonstrations and DPO preference pairs, teaching models the distinctions, exceptions, and boundaries your experts define.
“What I see in Teammately is a way to turn our experts’ knowledge into a lasting capability for AI development. It goes beyond collecting a dataset once. It gives teams the tools to keep building and improving their own.”

Powerful AI is within everyone’s reach. Build your advantage beyond the model. Teammately makes your expertise the difference.
Specialty Retailers
When relevance alone does not make a good recommendation.
A relevant product may still be the wrong recommendation. Customer intent, assortment priorities, availability, and acceptable alternatives change what an experienced merchant would choose.
Read solution
Business Software Companies
Acceptance standards for customer-specific AI work
Maintain acceptance standards across customer workflows as software changes. Assess product AI and internal customer-insight analysis, then develop better candidates.
“Teams need a way to see how far their evaluation dataset diverges from actual real-world usage and when they need to update their test cases.”
Travel Booking Platforms
Service judgment when standard booking flows stop resolving cases
Develop post-booking AI around specialist service judgment, supplier responsibilities, and useful handoffs. Construct exception coverage and assess existing responses.
Read solution
Airlines
Resolving complex passenger cases when disruption changes the options.
Passenger support combines fare rules, connection dependencies, limited rebooking options, and service recovery. Capture how experienced teams weigh those constraints, then test whether agents can reach feasible resolutions, explain trade-offs, and recognize when an exception needs expert attention.
Read solution
Vehicle & Equipment Manufacturers
Owner-support quality across product variants
Develop owner-facing AI around useful interpretation, clarification, and next-step guidance. Construct multimodal assessment cases across vehicle and product variants.
Read solution“Teammately is addressing many of the problems we’re trying to solve. I can see how our organization could benefit.”
Why we build
Machine intelligence is scaling fast. Humanity must stay in control.
We’re maximizing alignment per human effort by augmenting human judgment.
Explore our research directions
Where Teammately fits.
What starting involves.
How does Teammately compare with Scale, Surge, and Mercor?
Scale, Surge, and Mercor help teams build expert-informed datasets, evaluations, and model improvement programs. Their offerings combine expert workforces, technology, and support for designing and executing these programs.
Teammately is an agent-driven software platform for making your organization’s expertise part of how your AI learns and improves. Its agents prepare review materials, organize questions and context, and adapt elicitation as experts respond. They investigate the reasoning, exceptions, and conditions behind judgments, then develop findings into proposed rubrics, policies, and benchmark coverage. Agents undertake the preparation, inquiry, and interpretation; experts contribute judgment. Your team can inspect proposed rubrics and policies alongside linked expert evidence and cases, revise them, and decide which standards to adopt.
The value compounds as those standards develop. When an expert clarifies an exception or decision boundary, that finding can guide related benchmark cases, training-data synthesis, and harness experiments. Shared policies organize how standards apply across teams, while further expert contributions focus on what has changed or remains unresolved. Teammately is especially relevant when your team wants an ongoing capability to maintain and apply its expertise throughout AI development.
How does Teammately fit alongside LangSmith, Braintrust, or Langfuse?
Teammately can work alongside your tracing, evaluation, and development tools. Teammately connects coverage design and expert elicitation with rubric evaluation, harness experimentation, and training-data synthesis, helping your team turn its standards into tested AI improvements.
AI observability and evaluation platforms such as LangSmith, Braintrust, and Langfuse already help teams connect production observation with evaluation and dataset development. Within this alignment loop, coverage design across ontologies helps identify where changing user behavior diverges from what your benchmark represents. When connected, production interactions ground that design in actual usage, while expert standards and coverage objectives guide how the benchmark’s cases, combinations, and proportions evolve. Coverage also preserves rare, consequential situations that recent traffic may not contain.
Teammately also puts those benchmarks to work. Trialground evaluates candidates against your rubrics. Lemon Goal investigates failures, develops harness prototypes, and tests them in isolated sandboxes. Lemon Weave synthesizes training examples guided by expert policies and rubrics. Your engineers decide which changes to integrate and deploy; weights-training execution is separately scoped.
Stable benchmark versions give teams a shared basis for comparing improvements, while expert review and synthesis of neighboring scenarios help clarify decision boundaries, establish shared policies and rubrics, and determine how much each class of cases should influence the benchmark and the direction of development. Together, these capabilities connect your organization’s standards to benchmark design, evaluation, and tested improvements. Your existing tracing, evaluation, and development tools can remain part of that workflow, with data exchange scoped to your setup.
Do we need to upload production logs to get started?
No. You can begin with synthetic cases.
Lemon synthesizes realistic test cases as you design coverage across dimensions, topics, and scenarios, based on the reference materials you provide, without sharing sensitive production data.
This avoids the security risks and concerns associated with uploading production data for alignment. It also lets you start a project from scratch before you have production traffic.
Production logs can still help refine coverage around actual usage patterns when you choose to connect them, but they are optional add-ons.
How does Teammately handle ambiguous or conflicting expert judgments?
Different judgments can reflect missing context, competing priorities, or different expectations about where a rule applies. Teammately’s agents investigate those distinctions and prepare focused questions, comparisons, or reviews to clarify them.
Experts and accountable owners decide what should become a shared standard, where an exception applies, and what remains unresolved.
Do we retain ownership of what we build with Teammately?
Your expertise, standards, benchmarks, and development assets remain yours.
We don’t use your workspace data to train shared models or optimize harnesses for other workspaces without your permission. See our Privacy Policy and Trust Center for more on data handling.
Who operates Teammately, and where do we start?
Teammately provides a development workspace for your AI team and a dedicated participation interface for domain experts. Your AI team works with agents to direct elicitation, review standards and coverage, and evaluate candidate improvements. Engineers decide which development changes to adopt.
Experts contribute through prepared reviews, comparisons, forms, chat, and voice interviews. Agents handle the preparation, adaptive elicitation, and interpretation, so experts can focus on the judgments and distinctions that need their expertise.
We birdfood Teammately by building benchmarks across a wide range of use cases. You can adapt the guidance for Lemon’s configurable activities to your needs, or work with our team through the optional Forward Alignment program to develop it together.
Bring a development objective and the materials you already have. You can begin with a new initiative, a training requirement, or an existing system; a finished benchmark is not required.
Your expertise stays yours.
We do not use your workspace data to train shared models without your express written agreement. Control access by workspace and project. Private connectivity is available for data ingestion and model inference.
Explore our Trust Center
HIPAAUnder BAA
Build AI that meets your standards.
Tell us about the challenges you’re facing with your AI. We’ll show you how Teammately can help.